I measured my local LLM’s power bill and it costs less than a single $20 ChatGPT, Claude or Gemini subscription
XDA Developers
Picture: XDA Developers
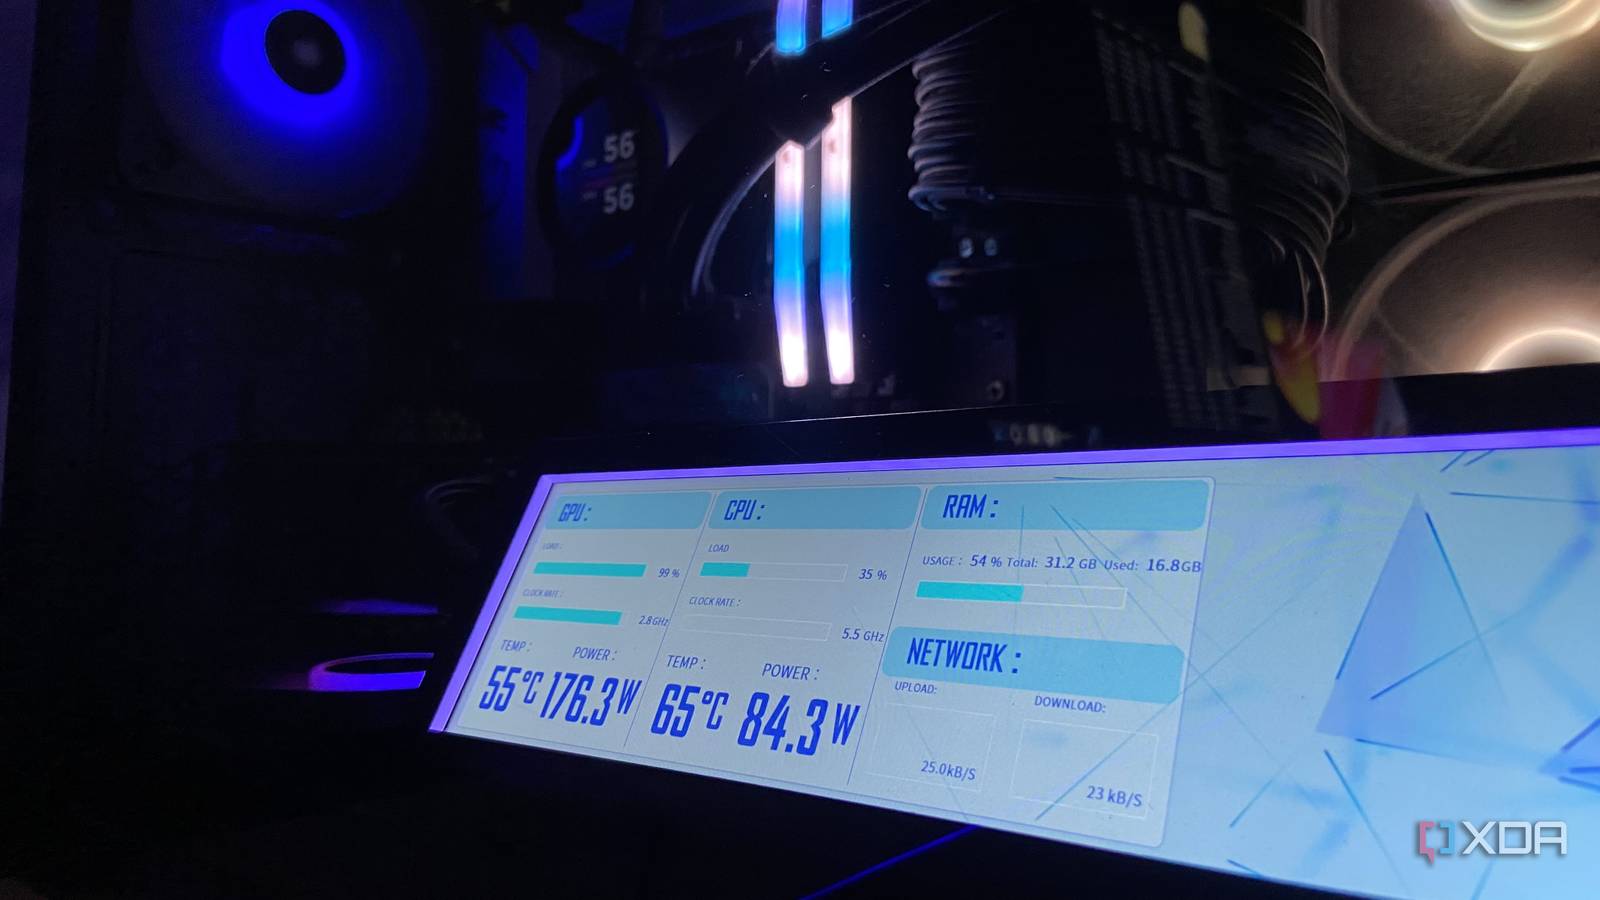
I've been a staunch proponent of self-hosting AI for a while now, and the points that I usually make are centered around data privacy and the fiscal cost of self-hosting your own models versus paying for a monthly subscription. One of the most frequent comments I get says that whatever I save by self-hosting my models is offset by my power bill, which always felt hyperbolic. To find out exactly how much local AI inference adds to my power bill each month, I benchmarked a model with llama-bench, the benchmark tool built into llama.cpp, logged power draw with HWiNFO and Nvidia's own nvidia-smi on my RTX 4070 Ti Super PC, and found that the cost is nowhere close to what I'd pay for a single AI subscription.
This report was first published by XDA Developers. What you see here is a brief excerpt. The full text is theirs.
Continue reading at XDA Developers
